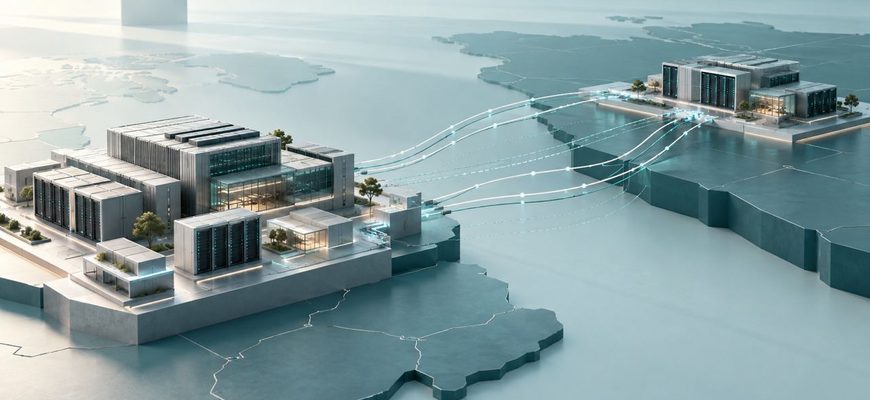
A growing SaaS company rarely starts with geographic redundancy. One well-managed production environment is usually simpler, less expensive and easier to troubleshoot than infrastructure spread across several locations.
That approach can work for years. But the decision changes when downtime becomes more expensive, customers enter new markets, data-location requirements appear or a single hosting region becomes an unacceptable business dependency.
The key question is not whether two regions are theoretically safer than one. It is whether a second region solves a defined business risk—and whether the company is operationally ready to manage the additional complexity.
- The business problem: one region has become a business dependency
- Translate the business case into infrastructure requirements
- 1. Recovery objectives
- 2. Workload scope
- 3. Geographic requirement
- 4. Operating model
- Four practical expansion options
- Option 1: Backup and rebuild in another region
- Option 2: Pilot-light environment
- Option 3: Warm standby
- Option 4: Active-active operation
- The main trade-offs
- Resilience versus complexity
- Recovery speed versus cost
- Consistency versus regional independence
- Automation versus controlled decision-making
- A practical implementation path
- Step 1: Document the business case
- Step 2: Map critical dependencies
- Step 3: Select the recovery model
- Step 4: Establish independent access and controls
- Step 5: Replicate and verify data
- Step 6: Test the complete recovery path
- Step 7: Assign ownership
- How to choose the second location
- Growth considerations after launch
- When a second region is premature
- Decision framework
- Frequently asked questions
- Does every SaaS company need a second hosting region?
- Is a second data center the same as a second region?
- Should the second region use a different hosting provider?
- Is active-active infrastructure always the most reliable option?
- How often should regional failover be tested?
The business problem: one region has become a business dependency
A single-region platform depends on the continued availability of one geographic location and the infrastructure serving it. Individual components may be redundant, but the business can still be exposed to a regional power event, network disruption, control-plane failure, configuration error or provider incident.
For an early-stage SaaS company, this risk may be acceptable. The team may reasonably prioritize product development, customer acquisition and reliable operation within one region.
The balance begins to change when one or more of the following conditions emerge:
- customers require stronger continuity commitments;
- an extended outage would create material revenue or contractual exposure;
- the company is expanding into a distant market;
- latency is affecting a business-critical user journey;
- data residency or customer procurement requirements limit where workloads can run;
- the existing location has become a concentration risk;
- recovery in the same region would not protect the business from a regional failure.
These are business triggers. They are more useful than broad goals such as “improving resilience” because they establish what the second region must accomplish.
Translate the business case into infrastructure requirements
Before selecting a location or provider, define the expected outcome. A second region built for faster customer access is not necessarily designed the same way as one built for disaster recovery.
1. Recovery objectives
Management and the technical team should agree on two limits:
- Recovery time objective: how long the service can remain unavailable before the impact becomes unacceptable.
- Recovery point objective: how much recent data the business could tolerate losing during recovery.
These objectives should reflect customer commitments, revenue exposure and operational reality. A near-zero target sounds attractive but may require substantially more complex replication, routing and testing.
2. Workload scope
Not every component needs to move at the same time. Identify which parts of the platform are essential to customer access and revenue.
The minimum recovery scope might include the application, primary data, authentication, DNS, secrets, essential third-party integrations and operational monitoring. Internal analytics or non-critical background processes may tolerate a slower recovery path.
3. Geographic requirement
The second location should address a specific geographic concern. That could be separation from the primary failure domain, proximity to a new customer base or compliance with contractual data-location requirements.
“Another data center” is not always enough. Two facilities can still share upstream networks, utility dependencies, management systems or regional risks. The team must understand what is genuinely independent.
4. Operating model
The company must decide who owns regional readiness, replication, failover decisions, access control and testing. If responsibility is unclear, the second environment may exist on paper while becoming unreliable in practice.
Four practical expansion options
Option 1: Backup and rebuild in another region
The company stores verified backups and infrastructure definitions outside the primary region, then rebuilds the service when needed.
This is usually the least expensive model, but recovery is comparatively slow. It depends on current backups, available replacement capacity, documented dependencies and a team capable of executing the recovery process under pressure.
Best suited to: businesses that can tolerate a longer interruption and want protection against permanent regional loss without maintaining a complete standby environment.
Option 2: Pilot-light environment
Critical data and a minimal set of services remain available in the second region. Additional application capacity is started during recovery.
This reduces rebuild time while avoiding the full cost of continuously operating two production environments. However, automation and testing must confirm that dormant components can be started and connected correctly.
Best suited to: growing platforms with meaningful continuity requirements but no need for immediate automatic failover.
Option 3: Warm standby
A smaller but functional version of the production platform runs in the second region. It receives replicated data and can be scaled when the primary environment becomes unavailable.
Warm standby can shorten recovery, but it introduces ongoing costs and operational work. Software releases, security controls, configuration and database changes must remain compatible across both environments.
Best suited to: established SaaS businesses for which several hours of downtime could have serious commercial consequences.
Option 4: Active-active operation
Both regions serve production traffic at the same time. This may improve geographic performance and reduce dependence on a single location, but it is the most demanding model.
Data consistency, session handling, routing, regional capacity and failure behavior must be designed deliberately. An error can propagate across both regions if they share the same deployment process, credentials or logical dependencies.
Best suited to: businesses with a justified need for continuous regional operation and the engineering maturity to manage a distributed platform.
The main trade-offs
Resilience versus complexity
A second region adds another possible recovery destination, but it also expands the system that can fail. Replication, traffic management and regional differences create new operational paths that must be monitored and tested.
Geographic redundancy improves resilience only when the secondary environment can operate independently enough to survive the incident it was designed to address.
Recovery speed versus cost
Faster recovery usually requires more infrastructure to be running before an incident. Backup-and-rebuild models minimize standby cost but take longer to activate. Warm or active environments reduce recovery time while increasing recurring expenditure.
The correct balance depends on the expected cost of interruption—not simply the monthly infrastructure bill.
Consistency versus regional independence
Standardized regions are easier to maintain. Yet excessive dependence on the same management services, credentials, automation pipelines or provider control plane can preserve a hidden single point of failure.
The goal is not maximum independence at any price. It is enough separation to protect against the risks included in the continuity plan.
Automation versus controlled decision-making
Automatic failover can reduce response time, but it can also redirect customers to an environment that is unhealthy, behind on data or too small for the load.
Some businesses benefit from automated traffic switching. Others need a controlled failover approved by an incident leader after data and capacity checks. The decision should follow the failure scenarios, not a general preference for automation.
A practical implementation path
Step 1: Document the business case
State the problem in measurable operational terms. Identify the outage scenarios, customer commitments, markets or regulatory requirements that justify expansion.
Also document what the project is not intended to solve. A disaster recovery region, for example, may not improve normal-day latency if it does not serve live traffic.
Step 2: Map critical dependencies
Create an inventory of the services required to deliver the essential customer experience. Include databases, object storage, authentication, DNS, certificates, secrets, monitoring, deployment systems and external integrations.
This exercise often exposes dependencies that are more important than the application servers themselves.
Step 3: Select the recovery model
Choose backup-and-rebuild, pilot light, warm standby or active-active operation based on the agreed recovery objectives. Avoid selecting the most advanced model by default.
The simplest model that meets the business requirement is usually easier to secure, test and operate.
Step 4: Establish independent access and controls
Confirm that authorized staff can reach and manage the second environment during a primary-region failure. Review credentials, privileged access, DNS control, documentation and emergency communication channels.
A secondary environment provides limited protection if the team cannot access it during the same incident.
Step 5: Replicate and verify data
Replication status alone is not proof of recoverability. The company needs a method for checking data freshness, integrity and application compatibility.
Backups should also remain part of the plan. Replication can copy accidental deletion, corruption or unauthorized changes into the second region.
Step 6: Test the complete recovery path
A useful test should cover more than starting servers. It should verify traffic routing, application behavior, data availability, customer authentication, monitoring and the ability to return to normal operation.
Record what happened, how long each step took and which assumptions were wrong. Use those findings to update the plan.
Step 7: Assign ownership
Give named roles responsibility for regional readiness, recovery decisions, communications and post-incident review. Documentation must be maintained as the platform changes.
Without ownership, a second region gradually drifts away from production until it can no longer support recovery.
How to choose the second location
The best location is not automatically the farthest location or the lowest-cost market. Evaluate it against the business requirement:
- distance from the primary operational risk;
- network connectivity to customers and the primary environment;
- availability of sufficient capacity during recovery;
- data residency and contractual restrictions;
- support coverage and escalation procedures;
- compatibility with the company’s automation and security model;
- the team’s ability to operate the environment consistently.
A company may choose a second region from the same provider for operational simplicity. Another may use a separate provider to reduce vendor concentration. Neither approach is universally correct: they protect against different risks and create different management burdens.
Growth considerations after launch
A second region is not a completed project. It becomes part of the production operating model.
As the business grows, review whether:
- the standby environment can handle the current critical workload;
- new services have been added to the recovery plan;
- replication still meets the agreed data-loss tolerance;
- recovery procedures reflect current staff and access controls;
- customer contracts have changed the required recovery targets;
- testing includes realistic capacity and dependency failures.
The second region should evolve with the product. Otherwise, the company may continue paying for infrastructure that creates confidence without providing dependable recovery.
When a second region is premature
Geographic expansion should not be used to avoid fixing weaknesses in the primary environment.
A company may be better served by improving backups, monitoring, deployment safety, capacity planning and local redundancy first if:
- the current platform has frequent application-level incidents;
- recovery procedures have never been tested;
- the team cannot reliably reproduce the production environment;
- ownership of infrastructure is unclear;
- there is no agreed recovery objective;
- the expected outage impact does not justify the continuing cost.
Two inconsistent regions are not safer than one well-operated region. Operational maturity should grow alongside geographic redundancy.
Decision framework
A growing SaaS business should consider adding a second hosting region when all three conditions are present:
- A defined business risk exists. A regional outage, geographic limitation or customer requirement has a material effect on the company.
- The required outcome is understood. The team has agreed recovery objectives, workload scope and geographic requirements.
- The company can operate the solution. It has the ownership, automation, documentation and testing discipline needed to keep the second environment ready.
If only the first condition exists, the next step is planning. If the first two exist but the third does not, the priority is operational readiness. When all three are in place, a second region can become a defensible investment in continuity and growth rather than an expensive symbol of resilience.
Frequently asked questions
Does every SaaS company need a second hosting region?
No. The decision depends on outage impact, customer commitments, geographic requirements and operational maturity. Many businesses should first improve resilience and recovery within their primary environment.
Is a second data center the same as a second region?
Not necessarily. Two data centers may still share regional utilities, network dependencies or management systems. The required level of separation should follow the failure scenarios the business wants to address.
Should the second region use a different hosting provider?
A separate provider can reduce certain vendor-level risks, but it also increases integration and operational complexity. Using the same provider may simplify management while preserving some shared dependencies. The choice should follow the company’s risk model.
Is active-active infrastructure always the most reliable option?
No. Active-active operation can support demanding availability and geographic performance requirements, but it creates additional data, routing and deployment complexity. A well-tested warm standby may be more dependable for a smaller team.
How often should regional failover be tested?
There is no universal interval. Testing should be frequent enough to detect changes in applications, access, dependencies and capacity before an emergency. It should also follow material platform changes. The schedule must match the company’s risk and recovery commitments.
Internal-link ideas How to Calculate the Business Cost of Hosting Downtime Suggested context: the discussion of outage impact and whether a second region is financially justified. Disaster Recovery Plans That Work During a Real Hosting Incident Suggested context: the implementation and recovery-testing sections. Single Points of Failure Business Owners Often Miss Suggested context: the dependency-mapping section. When a Growing SaaS Should Move Beyond a Single Server Suggested context: the opening discussion of infrastructure maturity. How to Evaluate Geographic Risk Before Expanding into Europe Suggested context: the location-selection section. Should Your Business Use More Than One Hosting Provider? Suggested context: the vendor-concentration discussion.